Peptides Research Library
A searchable library of plain language summaries of peer reviewed peptide studies, pulled from PubMed, then summarized and sorted by study quality with Claude. The live site has 691 summaries across 90 peptides.
Period
- Apr–May 2026
Role
- Sole engineer
Type
- Live site
Tools
Why
I was reading about peptides and kept running into the same problem: the studies are behind dense abstracts, and most of what's online about them is forum posts and marketing. I wanted one place that tells me what the actual research says and how much to trust it.
How it works
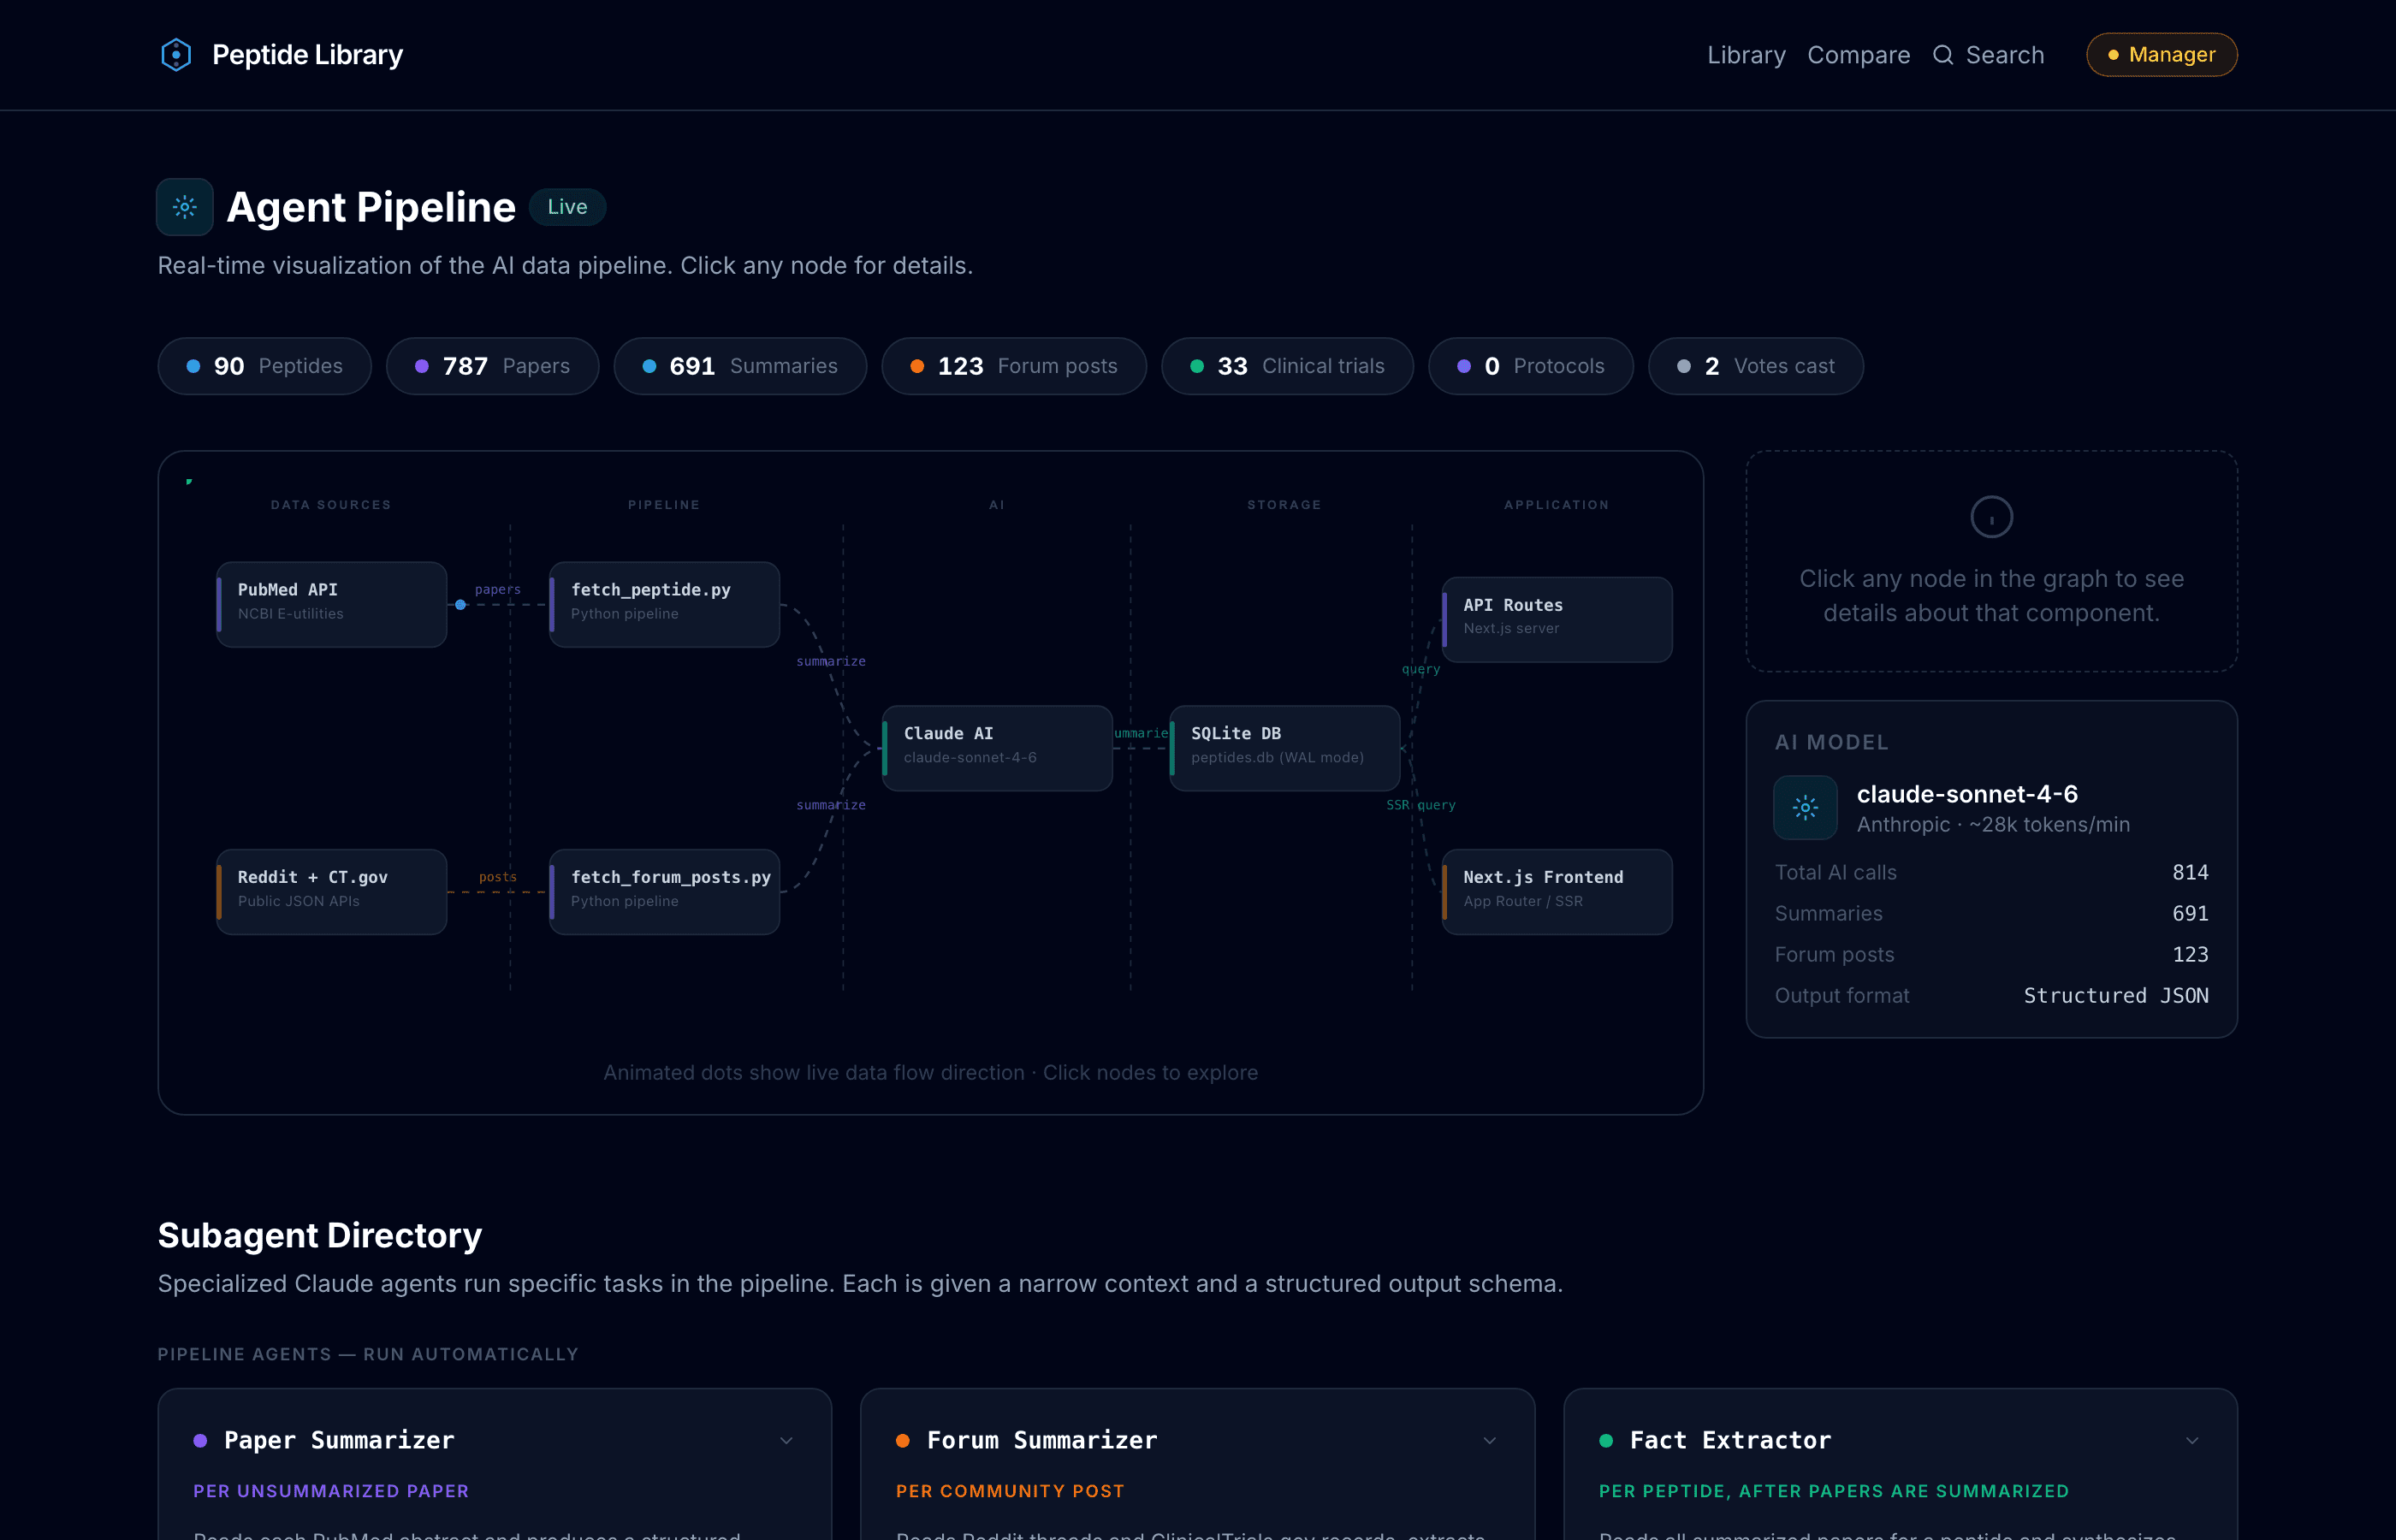
A set of Python scripts pulls papers for each peptide from PubMed. Claude summarizes each one into a plain English summary, three key findings, a study type, and a trust level: trusted for randomized and controlled studies, semi trusted for reviews and case reports, and speculative for the rest. Another pass pulls together per peptide facts like the usual route and what it's commonly studied alongside. Reddit and ClinicalTrials.gov posts get summarized separately and kept in their own tab so they don't mix with the papers. The scripts sleep between calls to stay under the API rate limit.
The site is Next.js on SQLite, with a category grid, search, side by side comparison, and a pipeline page that animates how data flows through with live counts. It runs in Docker on Fly.io and scales to zero when nobody's using it.
Limits
The live site is a snapshot from late April. My local copy has grown to about 1,200 summaries but I haven't redeployed it. I also built a fact checking step that never ended up recording anything, so nothing on the site has been checked beyond the model's own summary. This is a reading tool, not medical advice.